

“It's almost like cheating”, I thought.
Slowly, I leaned back in my chair, laced my fingers behind my head, and looked at the terminal output.
“It's almost like cheating!”, I repeated, this time out loud.
I had just finished the implementation of my agentic AI setup and wanted to do a test: something simple, something quick. “Hey, agent, put on a show for me. Showcase your ability to write and read files, to access the internet, to author scripts and to analyse the results” – I prompted. It didn't take long for the agent to structure a plan and start working: it fetched the NCBI SARS-CoV-2 reference genome accession number and downloaded the corresponding FASTA file, wrote a script to analyze its GC content profile, executed it and reported the results – all in 41 seconds. It even had time mid-run to self-correct, autonomously, a couple of times.
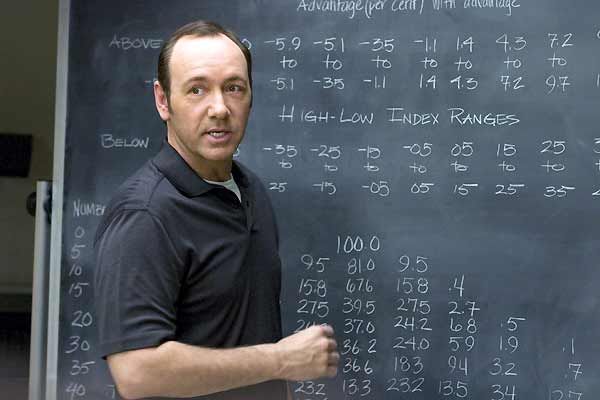 I just felt like Professor Micky Rosa in the movie 21, where he puts together a group of talented MIT students to bet – and win – at the blackjack tables in Las Vegas casinos. Through a series of card counting techniques, they stack the odds in their favour and make large sums of money. I bet you have never counted cards in a casino – or have you? – but despite what is commonly believed, counting cards is not illegal. It just feels so because of the definitive advantage it gives to whoever is able to do so in an efficient manner.
In the same way, I had just realized, in 41 seconds, that agentic AI can be the card counting of computational biology. Those who can efficiently harness it will have a definitive advantage in the biotech and biopharma competitive market.
But what is agentic AI, anyway?
In the last few years, we have all gotten used to the now standard large language models (LLM) – chatty, knowledgeable, with boot-licking tendencies. You type a prompt into a box and you get text back. It's all words and no action. It cannot do anything by itself.
On the other hand, an agent is a goal-oriented, code-executing and self-correcting engine. An agent is a brain with a body:
- The Brain: handles reasoning, language and logic through the use of an LLM.
- The Body: connects the brain to the execution environment, computational tools and memory systems through the use of so-called harness software.
Instead of waiting for step-by-step instructions, an agent ingests an objective, breaks it down into actionable sub-tasks, writes and executes code, evaluates the results and fixes its own mistakes when things go wrong, all under a series of human-made, carefully crafted instructions, guardrails and scientific standards.
From Long Turn-Around Times to Seizing the Opportunity
 Imagine sitting with your team and deciding to go for a re-clustering of your single-cell RNA-seq data to leverage novel, promising markers that just arrived from the lab. The timing is critical. A narrow window of opportunity just opened before a major board meeting or a critical funding round. Unfortunately, traditional analytical cycles involve long turn-around times and feedback loops. Whether relying on internal teams or external consultants, turning raw data into executive insights can take weeks or months. Meanwhile, your wet-lab scientists lack the specialized bioinformatics bandwidth to run the analysis themselves.
Resigned, you sigh and make peace with it – another strategic opportunity missed. However, with careful planning, an agentic AI pipeline could have saved the day. It would have been able to not only bridge the initial expertise gap between the wet-lab scientist and the technical, in-silico analysis – use of natural language for prompting and self-correcting capabilities – but also compress weeks or months of waiting into days or hours. By autonomously authoring, running and validating re-clustering scripts, the agents could have delivered board-ready figures just in time to secure an investor's milestone, or ensure that the funding round goes your way.
From Fragile Pipelines to Self-Healing Workflows
 Of course, the turn-around gap between need and insight has been a challenge for quite some time already. Starting from a one-off analysis designed and executed by a computational biologist, one day somebody in the team figured out that the same analysis was going to be needed multiple times in the future. This led to the development of customized pipelines, typically written in Python, R or NextFlow. But think back to just this week: how many times did your metabolomics pipeline crash due to messy metadata, memory overflows, or the file names were simply too long (real story). This is especially the case in a research environment, where the field moves exactly at the same pace that bioRxiv is able to push articles online.
In contrast, agentic pipelines are resilient and adaptive. Because they possess semantic reasoning, an agent doesn't simply crash when faced with a malformed CSV or a missing header. Instead, it inspects the error, diagnoses the mismatch, re-formats inputs on the fly, and adjusts execution dynamically. Where traditional pipelines are rigid tracks that derail at the smallest pebble, agentic pipelines act like self-navigating vehicles, continually auto-correcting around data friction.
From Resource Shuffling to Lightning Speed Projects
It is fair to say, however, that some teams have a dedicated team of bioinformaticians and computational biologists at their disposal. These experts can be deployed, if you are lucky enough, in a matter of days or hours, shortening turn-around times and bridging technical expertise – at least on paper. The reality hits harder. Most of the time, the correct expert is not available; or assembling the correct team takes longer than anticipated; or simply the personnel onboarding is disproportionately costly with respect to the task at hand; or even worse, after finding the resources, assembling the team, and finishing the onboarding, the team is pulled away from your project to meet the needs of somebody else's project – of course way less important than yours.
 This is why, when you grab and assemble the ideal team, you want them to focus on what matters. It is all about efficiency. You don't want PhD-level scientists focusing on writing routine scripts, correcting CSV column formatting issues or fixing typos in a source code file.
An agentic AI-native team, on the other hand, works differently. By operating carefully implemented and customized agentic pipelines, the biologists can refocus their attention on what their human mind excels at: context, scientific judgement and creativity. In the background, the agents, under expert human supervision, take care of writing routine scripts, correcting input formatting issues and fixing bugs in the code. In the foreground, scientists find new potential targets, novel drug modes of action and develop revolutionary hypotheses that push the envelope. This change of paradigm results in your project progressing at lightning speed, while others slow down and stall, risking getting left behind by the guys upstairs.
Count the Cards With Your Agentic Edge
Ultimately, deploying agentic AI in computational biology is all about hitting investor milestones, securing patents ahead of competitors, reaching grant deadlines early, and accelerating the delivery of therapeutics to patients.
If you want to feel like you are just cheating, I can help you design, deploy and maintain these agentic workflows tailored to your specific research goals.
Schedule a strategy meeting with Jonas at Omics Intelligence and start counting the cards.